
Guide
What is IDP? Understanding intelligent document processing
Published
AT A GLANCE
A beginner's guide to document intake, classification, extraction, validation, human review and controlled export, with a fictional invoice workflow.
THE PROCESS AT A GLANCE
From document to decision
A simple review pattern to adapt to each workflow.
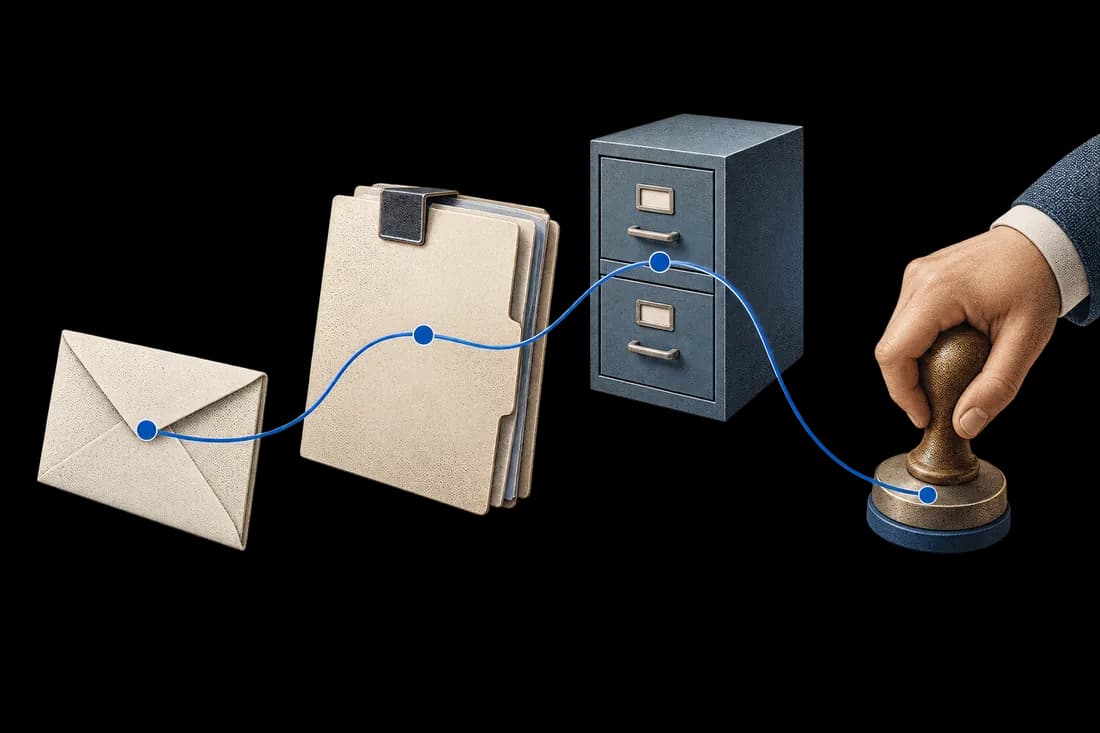
- SourceIdentify the document and source of truth.
- ExceptionShow what is missing or does not match.
- DecisionRoute the exception to the responsible person.
IDP means intelligent document processing. It combines document-reading and information-extraction techniques with classification and validation. In an operational workflow, these capabilities help turn incoming documents into structured records and route unresolved cases to people. OCR can be one component; IDP covers more of the process.
Follow one invoice through the workflow
Fictional example: a supplier emails an invoice and a delivery note. The intake step retains both files and the message. Classification proposes which file is the invoice and which is delivery evidence. Extraction proposes supplier, references, dates, lines and amounts. The original files remain attached to the case.
Validation then checks required fields, totals, duplicates and the relevant purchasing records. A missing order reference produces a named exception. A reviewer compares the source with the proposed data, resolves the issue and approves the appropriate next step. The destination system records the import result and its identifier.
Separate the jobs of models, rules and people
A model may help recognize a document type or suggest a field from an unfamiliar layout. Stable rules are suitable for arithmetic, required fields and approved catalogue mappings. A person resolves ambiguity or authorizes a consequential action. A useful design specifies the owner of each step rather than asking one model to do everything.
Generative AI is optional. Some workflows work with OCR, templates and rules; others need more flexible extraction. Before building a custom pipeline, compare the capture, approval and import features already available in your accounting or ERP software.
Design the exception path first
Define what happens when a page is missing, a supplier is unknown, a total is inconsistent or an import times out. Each exception needs a reason, an owner, visible evidence and a next action. Preserve the original value and the correction history. Do not fill a missing reference with a plausible invention.
Separate 'read', 'checked', 'approved' and 'exported'. A document can be read successfully while failing a business check. An approved case can still fail during transfer. If an import is interrupted, check the destination before retrying so the same invoice is not created twice.
Evaluate the whole process
Use representative documents with ordinary cases and known exceptions. Record field corrections, missed exceptions, review time and destination acceptance. Compare total handling effort with your current method. A faster reader is not useful if the team spends longer repairing its output.
For a first pilot, choose one document type, one entry channel, one destination and one owner. Agree on the errors that must stop the case and the evidence required for approval. Extend the scope only after the workflow handles both routine cases and recovery.
Sources and further reading
IBM: intelligent document processing
Apply this to your workflow
To scope a document workflow, prepare a permitted example, the required fields, your current system and the person who reviews exceptions. Begin with synthetic examples when confidential data is unnecessary.
Related reading
Automating supplier invoices: from email to a case ready for review
Connect invoice intake, extraction, duplicate checks, document matching and a controlled ERP import with human review.
Read article
How can email, ERP and spreadsheets share one workflow without replacing the ERP?
Set clear system ownership, connect one recurring handoff and make exceptions visible before expanding.
Read article